Structuring Liferay AI Hub: When to Build an Agent vs. Write an Instruction
This is LR Tools’ rewrite of a practical field guide by David H Nebinger on Liferay.dev, written after he built a chatbot on AI Hub and ran into design questions the official docs don’t fully cover. The AI Hub integration documentation is the right starting point for setup; this is about the design decisions that come after setup.
The building blocks
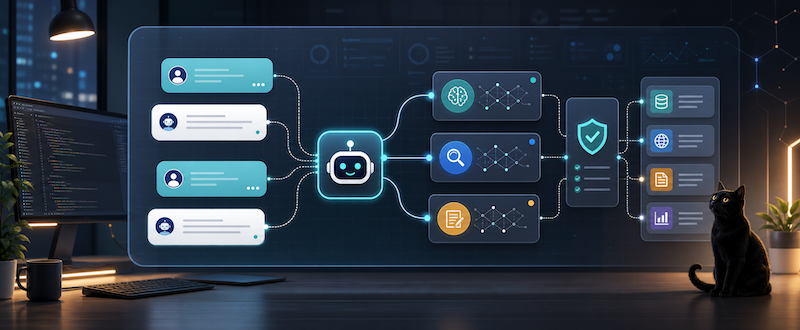
AI Hub gives you five kinds of pieces to assemble:
- Agent — a single task, built as its own workflow canvas, with input variables, one output variable, and optional data sources and guardrails attached. Liferay ships several built-in agents (tone adjustment, grammar fixing, search) that you can’t edit; anything custom is yours to build.
- Instruction — a rule that applies across many agents at once, rather than something you’d copy-paste into every prompt: brand voice, a compliance rule, a “reply in the user’s language” policy. Each instruction pairs the rule with what to say when it fires, and a scope for where it applies.
- Guardrail — a safety check enforced outside the model itself, so it holds even against a prompt that tries to argue around it. Guardrails run against either the incoming user message or the model’s reply, and attach per agent.
- Data source — a crawled site (same domain, a few link levels deep, capped page count) that an agent can search semantically for grounded answers, rather than relying on the model’s own knowledge.
- Supervisor — the router in front of everything: the CMS editor’s AI Assistant, or a deployed Chatbot scoped to a chosen set of agents. It reads the request and picks (or combines) the best-matching agent.
One detail that’s easy to underrate: an agent’s title and description aren’t just labels for a human browsing a list — they’re the primary signal the supervisor uses to decide which agent handles a given request. A vague description means an agent that works perfectly might simply never get picked.
Deciding between an agent and an instruction
The distinction that matters: an agent does a piece of work, an instruction shapes how work gets done. If a user needs something performed — translated, summarized, searched, generated — that’s an agent, because it needs its own inputs, output, and workflow. If instead you want one rule to hold everywhere (“never provide financial advice,” “always match the user’s language,” a brand tone), that belongs in an instruction, defined once and inherited by every agent it applies to instead of repeated in each one’s prompt. And if the rule has to survive someone actively trying to talk the model out of it — filtering PII, blocking a jailbreak attempt — that’s neither an agent nor an instruction; it’s a guardrail, because only a guardrail runs outside the model’s own reasoning.
Treating custom agents as something to create sparingly matters practically too: each one is a workflow you now maintain, and some AI Hub tiers cap how many custom agents you can have.
Prefer several small agents over one that branches internally
Say you need to handle translation into Spanish, French, or German. It’s tempting to build one agent with a branch for each language. Building three small, single-purpose agents instead is usually the better call, for a reason that comes straight from how the supervisor works: it picks an agent by comparing the request against that agent’s description, and one large forking agent only has one description to offer. A request for French translation has no way to signal that it needs the French branch specifically — the router can only see “translation,” not what’s inside. Separate agents each advertise exactly what they do, which is what makes routing reliable, and it has knock-on benefits too: each agent’s guardrails and data sources apply only where they’re actually needed, permissions can be scoped per agent, and a focused workflow is far easier to test than one canvas full of conditional paths.
Internal branching still has its place — when the steps are things the user should never need to choose between (detecting a language before translating, normalizing input before processing), or when splitting would mean duplicating a large shared setup for a handful of minor variations. The rule of thumb: branch inside an agent only for steps the user shouldn’t have to name themselves; give every user-visible capability its own agent.
Writing prompts that actually route well
An agent’s prompt is its standing instruction to the model; the user message template is where the actual input gets injected via placeholders. A prompt that routes and performs reliably generally does four things: gives the model a clear role to play, states the one job it’s doing and nothing more, calls out the edge cases explicitly (what to do if the input doesn’t need processing, or arrives already in the target state), and pins down exactly what shape the output should take. That last point matters more than it looks — if the supervisor is going to feed one agent’s output into another, an agent that adds commentary or explanation around its actual answer breaks that chain.
Keep each agent doing one job (it matches how the router thinks about them), put reusable policy in an instruction instead of repeating it in every prompt, and — again — write the description to name the trigger and the result plainly, rather than something generic that leaves the supervisor guessing.
Writing instructions that hold up
An instruction is really two things bundled together: the rule, and what the agent should actually say when the rule applies — leaving out the second half is a common mistake, since “don’t do X” without a fallback response leaves the model to improvise one. Scope each instruction deliberately (Liferay lets you restrict one to the CMS authoring assistant, to a public-facing chatbot, or to both) so a rule meant for one audience doesn’t reshape the other. And remember instructions layer on top of Liferay’s own built-in system-level rules, which take precedence and can’t be overridden — design instructions to work within that boundary, not around it.
Guardrails: the part that isn’t optional for anything public-facing
Guardrails run through Google Cloud Model Armor rather than through the model itself, which is exactly why they hold even when a prompt is crafted specifically to defeat a rule. Input-side guardrails screen what the user sends — filtering malicious links, catching prompt-injection and jailbreak attempts, and screening for sensitive personal data before it ever reaches the model. Output-side guardrails screen what the model sends back, with adjustable thresholds across categories like hate speech, dangerous content, sexually explicit content, and harassment.
The practical guidance here is mostly about where to spend the cost: guardrails add latency and cost per run, so a public chatbot facing the open internet warrants the strict end of both input and output screening, while an internal authoring assistant used by trusted staff can usually run lighter. Pair input and output screening together rather than relying on just one side, turn on multilanguage detection if you expect non-English input, and — the one rule that shouldn’t be negotiable — never substitute a prompt instruction for a guardrail on anything actually safety-critical. A prompt is a request; a guardrail is an enforcement.
Give components ERCs that mean something
Every AI Hub component — agent, chatbot, instruction — gets an External Reference Code, and by default that’s an opaque generated UUID. It costs almost nothing to replace it with something legible instead, along the lines of PROJECT-RESPONSE-FORMATTING for an instruction that governs response formatting. A meaningful code is easier to reference in a ticket or a runbook than a UUID, lines up consistently across dev/test/production instead of needing to be reconciled by hand, and — if headless API access to these components ever ships — is exactly the stable key such an API would need. Pick a simple convention early, something like PROJECT-COMPONENT_TYPE-PURPOSE, and apply it from the first agent you create rather than retrofitting it once you have dozens.
The shape of a well-built AI Hub setup
Put together, a project that’s applied all of this ends up with: a handful of narrowly-scoped agents, each with a description that plainly states its trigger and result; shared policy and tone living in instructions rather than duplicated across prompts; guardrails tuned to match how exposed each agent actually is; and components named well enough that six months from now, someone other than the original author can tell what each one does at a glance.
This article is LR Tools’ rewrite of the original post by David H Nebinger — read it on Liferay.dev for the author’s own framing.
Dieser Artikel ist adaptiert von: David H Nebinger, Liferay.dev